The Bicycle to Car Fallacy: Architecting Your MVP for Scale Without Over-Engineering
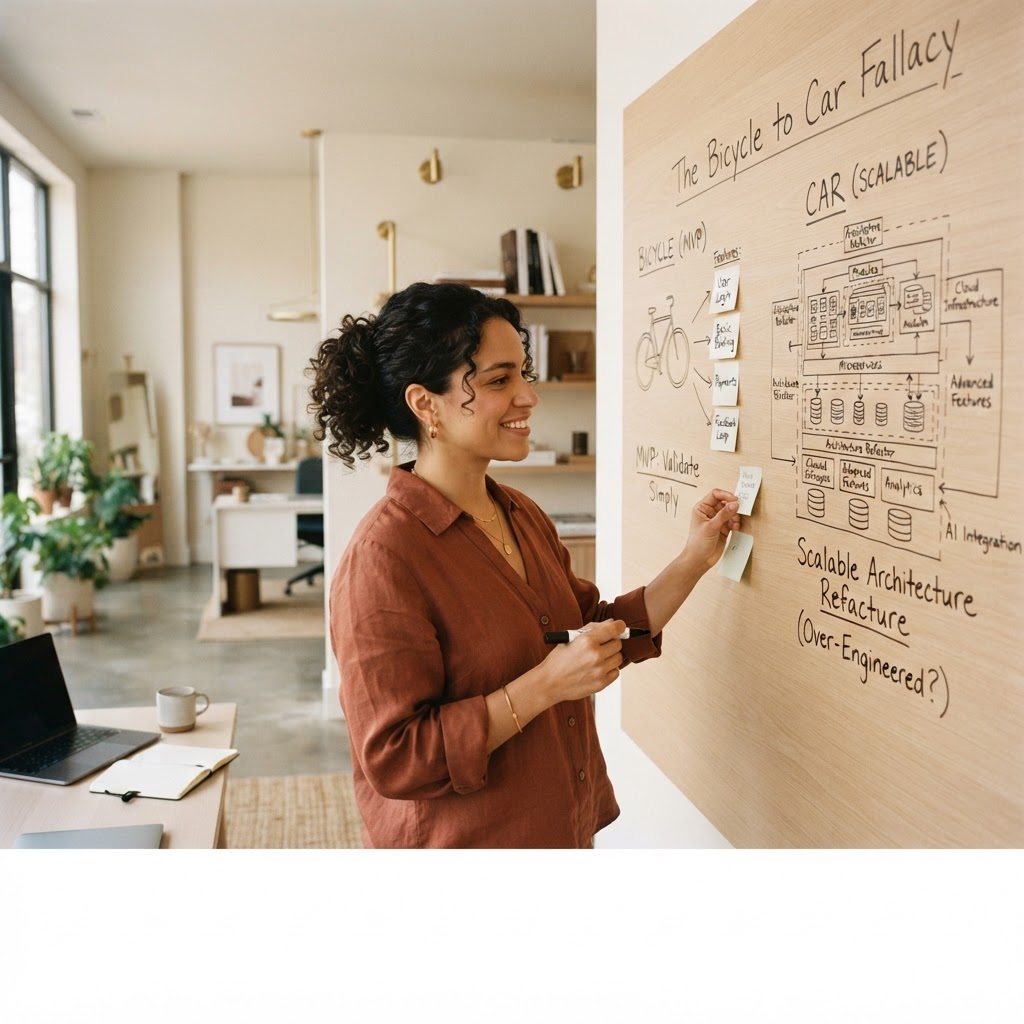
Most founders try to upgrade their MVP into a scalable product the same way you'd bolt an engine onto a bicycle. It does not work. The transition from MVP to scalable system should be treated as a fresh design decision informed by what you learned, not an incremental patch job on code that was never meant to carry that weight.
The Core Misconception: Upgrading vs. Redesigning
Founders often assume scaling means adding features to existing components until the system can handle more load. That mental model is the trap. A bicycle cannot become a car through incremental upgrades. You do not add a roof to a bicycle and call it a car; you design a car using what you learned about the roads, the weather, and the passengers from riding the bicycle.
The same logic applies to software. Your MVP's database schema, authentication flow, and API structure were built to answer one question fast: does anyone want this? Once you know the answer, the requirements change entirely. Trying to force the old structure to serve new requirements creates fragile systems that break in unpredictable ways. As one framework for this transition puts it, the redesign should be treated as a design process built on MVP lessons, not an engineering task of upgrading existing parts (zaitsevartem.com).
Building Modular From Day One
The way to avoid a painful rebuild later is not to over-engineer the MVP. It is to make specific, low-cost architectural choices that keep your options open. This is the difference between premature scaling (building for millions of users you do not have) and modular discipline (building in a way that lets you swap parts later without rewriting everything).
Practical steps to stay modular without slowing down delivery:
- Isolate features behind clear interfaces. Even if two features share a database in your MVP, define the boundary between them as if they might someday live in separate services.
- Separate data ownership early. Give each core domain (users, billing, core workflow) its own schema or clearly scoped tables, even inside a single monolith.
- Avoid shared mutable state across features. When two parts of your app quietly depend on each other's internal data, extraction later becomes a rewrite instead of a move.
- Pick boring, well-documented frameworks. Exotic tooling optimizes for a demo, not for the next engineer who has to extend it.
- Write acceptance criteria before code. Clear criteria force you to define what "done" means for a feature, which naturally exposes boundaries. Our guide on MVP acceptance criteria walks through this in detail.
A startup that adopts this approach can evolve incrementally, isolating features so the system grows without requiring a total rewrite (wednesday.is). The goal is not perfection. It is optionality.
Technical Debt as a Bridge Loan, Not a Trap
Speed matters in an MVP, and some technical debt is a rational trade-off. The useful mental model is a bridge loan: you take it on deliberately, you know what it costs, and you have a plan to repay it. What sinks startups is not the debt itself, it is debt taken on without anyone tracking it.
Manage MVP-era technical debt with intention:
- Keep a short, visible list of shortcuts taken and why.
- Flag any shortcut that touches money, security, or user data as higher priority to repay.
- Revisit the list at every major milestone, not just when something breaks.
- Treat undocumented shortcuts as the real risk, not the shortcuts themselves.
This is different from ignoring architecture altogether. A shortcut you wrote down and understand is manageable. A shortcut buried inside a rushed pull request with no note is the kind of debt that compounds without warning.
A Hypothetical Example: From Booking Widget to Marketplace
This is a hypothetical example, not a real client case. Imagine a founder building an MVP for a service that lets small studios book freelance instructors. The MVP is a single booking form, one database table for sessions, and a simple email notification when a session is confirmed.
The MVP proves the demand. Studios want it. Now the founder wants to add payments, instructor ratings, and multi-location scheduling. If the team tries to bolt these onto the original single table and the original notification script, every new feature increases the odds of a scheduling conflict or a payment race condition. That is the bicycle-with-a-roof problem.
Instead, the redesign phase treats bookings, payments, and identity as separate domains from day one of the new build. Bookings own their own scheduling logic. Payments are isolated behind a clear interface so the payment provider can change later without touching booking code. Identity and permissions are handled once, centrally, instead of duplicated per feature. The MVP's lessons, which features studios actually used, what data mattered, where the friction was, inform this new design, but the code is deliberately rebuilt rather than stretched.
Signals That It's Time to Redesign
Not every MVP needs a rebuild. Watch for these signals instead of arbitrary timelines:
- You are duplicating logic across features because there is no clear owner for shared data.
- Every new feature request requires touching the same fragile file or table.
- Onboarding a new engineer takes days because there are no clear module boundaries.
- Your team is afraid to change core logic because nobody fully understands the dependencies.
- User growth or new use cases are forcing changes to your original data model. Mapping this out before you design new screens is worth doing early, as covered in how to map your MVP data model.
A critical reason MVPs fail to scale is rarely the specific technology chosen. It is the absence of clear module boundaries and explicit service interfaces established early, which makes later extraction mechanical rather than heroic (newzenconsultancy.com).
Common Mistakes Founders Make
- Over-engineering the MVP to "future proof" it, which slows validation and burns runway on infrastructure nobody uses yet.
- Under-engineering the redesign by trying to patch the MVP instead of rebuilding the parts that need it.
- Ignoring the technical debt list until a launch deadline forces a scramble.
- Skipping onboarding feedback that would have shaped the redesign. Real usage patterns from your first users, discussed in designing MVP onboarding for your first ten users, often reveal which modules matter most.
- Rebuilding everything at once instead of redesigning the specific domains under strain.
Tradeoffs to Weigh
There is no version of this decision without tradeoffs:
- Moving fast on the MVP means accepting some rework later. Moving slow to "do it right" the first time risks building the wrong thing entirely.
- Modular boundaries add a small amount of upfront design time but pay off if you need to extract a service later.
- A full redesign costs more time and money than a patch, but a patch on a strained system often costs more in debugging and downtime over time.
Pre-Redesign Checklist
Before committing to a rebuild, confirm:
- [ ] You have validated real demand, not just interest, from actual usage.
- [ ] You have a documented list of technical debt and why it exists.
- [ ] You know which modules are under the most strain and why.
- [ ] You have clear acceptance criteria for what the next version must do.
- [ ] Your data model reflects what you learned, not just what you assumed at MVP stage.
- [ ] You have decided which parts of the MVP to keep, which to isolate, and which to rebuild.
For a broader walkthrough of moving from a working prototype to a reliable launch, see building an MVP from first workflow to reliable launch.
The bicycle-to-car analogy is useful because it resists the instinct to patch. Your MVP did its job if it taught you what to build next. Treat the next phase as a design decision, not a repair job, and you will avoid both over-engineering too early and rebuilding in a panic too late.
If you are approaching this transition and want senior engineers, assisted by AI, to help you redesign with the right boundaries from the start, reach out through Golden Ticket.
Frequently Asked Questions
What does the bicycle to car fallacy mean for MVP development?
It refers to the mistaken belief that you can upgrade an MVP into a scalable product through incremental patches, the way you cannot turn a bicycle into a car by adding parts. Scaling usually requires a redesign informed by MVP lessons, not incremental upgrades to the same components.
How do I know when my MVP needs a redesign instead of a patch?
Watch for signals like duplicated logic across features, fragile shared files that every new feature touches, slow onboarding for new engineers due to unclear boundaries, and a data model that no longer fits real usage patterns you have observed.
Is technical debt always bad in an MVP?
No. Technical debt taken on deliberately, with a documented reason and a plan to address it, functions like a bridge loan. The real risk is undocumented shortcuts that nobody tracks or plans to repay.
Does building a modular MVP take longer than building a quick, unstructured one?
It adds a small amount of upfront design time, such as defining clear module boundaries and data ownership, but this tends to be much less costly than extracting tangled logic later when you need to scale specific parts of the system.