The reading room
Explore the ideas.
Articles on building apps, working with AI, and finding the right product idea.
Start with a complete topic guide
The Traction-Validation Paradox: Why Early-Stage Founders Must Prioritize Behavioral Signals Over Vanity Metrics
Early traction can feel like validation when it is really just flattering noise. This article shows founders how to build a pre-launch measurement framework that separates genuine behavioral signals, like pilot commitments and retention after friction, from vanity metrics that lead nowhere.
The Execution Guardrail Dilemma: Balancing Agent Autonomy with Workflow Correctness
Agent autonomy and workflow correctness do not have to be opposing forces. This article shows founders how to build execution-time guardrails, like precondition checks, hard execution limits, and rollback mechanisms, that keep agentic workflows safe without stripping out their flexibility.
The State-Managed Agent Shift: Moving Beyond Prompt-Response Loops in AI MVPs
Simple prompt-response loops cannot verify their own outputs, which lets errors compound silently as your MVP scales. This article walks through the practical steps, tradeoffs, and a worked example for adopting state-managed agentic architecture early.
The Manual-First Validation Trap: Why Testing Value Before Technology Is the Only Way to De-Risk AI MVPs
Before investing in AI development, founders should manually perform the intended task and deliver the output to real users, then measure behavior rather than compliments. This manual-first approach isolates the riskiest assumption and prevents costly prompt engineering on unvalidated ideas.
The Eval-Observability Gap: Why Watching Your Agents Isn't the Same as Improving Them
Observability shows you what your AI agent did, but only evaluation tells you if it was good, and founders often confuse the two. This article walks through a practical framework for turning raw agent logs into a feedback loop that actually improves reliability.
The Evaluation Loop Gap: Building Pre-User Quality Assurance into AI MVPs
Most AI MVPs ship without a formal evaluation loop, which means the first signal of a quality problem is an angry user instead of a caught test case. This article walks founders through building a lightweight, pre-launch quality assurance system using a golden dataset, scoring rubric, and monitoring layer.
The Signal-to-Cost Ratio: Optimizing Validation Experiments for Maximum Learning
Founders often default to building features as their validation method, which is usually the most expensive way to learn something cheaper tests could reveal. This article offers a systematic process for matching each validation question to its lowest-cost, highest-signal test.
The Attribution Gap: Mapping Agentic Failures to Root Causes in Production
Agent failures rarely surface where they originate, which means simple error logs cannot tell founders what actually went wrong. This article maps a practical, closed-loop attribution framework for finding true root causes and building recovery loops that improve over time.
The Reversibility Audit: Identifying High-Stakes Architectural Decisions in AI MVPs
Not every technical choice carries the same risk. This article shows founders how to run a Reversibility Audit to separate low-stakes tool swaps from the architectural decisions that are genuinely expensive to undo.
The Kill-Threshold Framework: Setting Pre-Evidence Standards to Prevent Founder Bias
Most validation efforts fail quietly because founders set their standards after seeing the evidence, not before. This article shows how to write binding kill thresholds for pain, spend, and reach so weak signals get rejected instead of rationalized.
The Reliability Contract: Moving From Task Success to State-Bound Evidence
Task success metrics hide the operational flaws that cause production incidents in agentic coding. This article shows founders how to build a reliability contract around state preservation, provenance, and verification instead.
The Integration Threshold: When to Move From Chat-Based AI to System-Integrated Agents
Chat-based AI interfaces are easy to validate but limited in value, while system-integrated agents carry real risk if adopted too early. This article gives founders a concrete framework and readiness checklist for knowing exactly when to make that transition.
The Commitment Gap: Distinguishing Between User Sentiment and Behavioral Demand
Polite interest and real market demand are not the same thing, and confusing them is one of the most expensive mistakes a founder can make. This article shows how to test for behavioral commitment, not just opinions, before investing in a build.
The Durability Gap: Distinguishing Agent State From Workflow Persistence
Agent reasoning state and durable workflow state are often treated as the same thing, leading to silent data loss when agentic MVPs hit production failures. This article explains how founders should architect the boundary between the two.
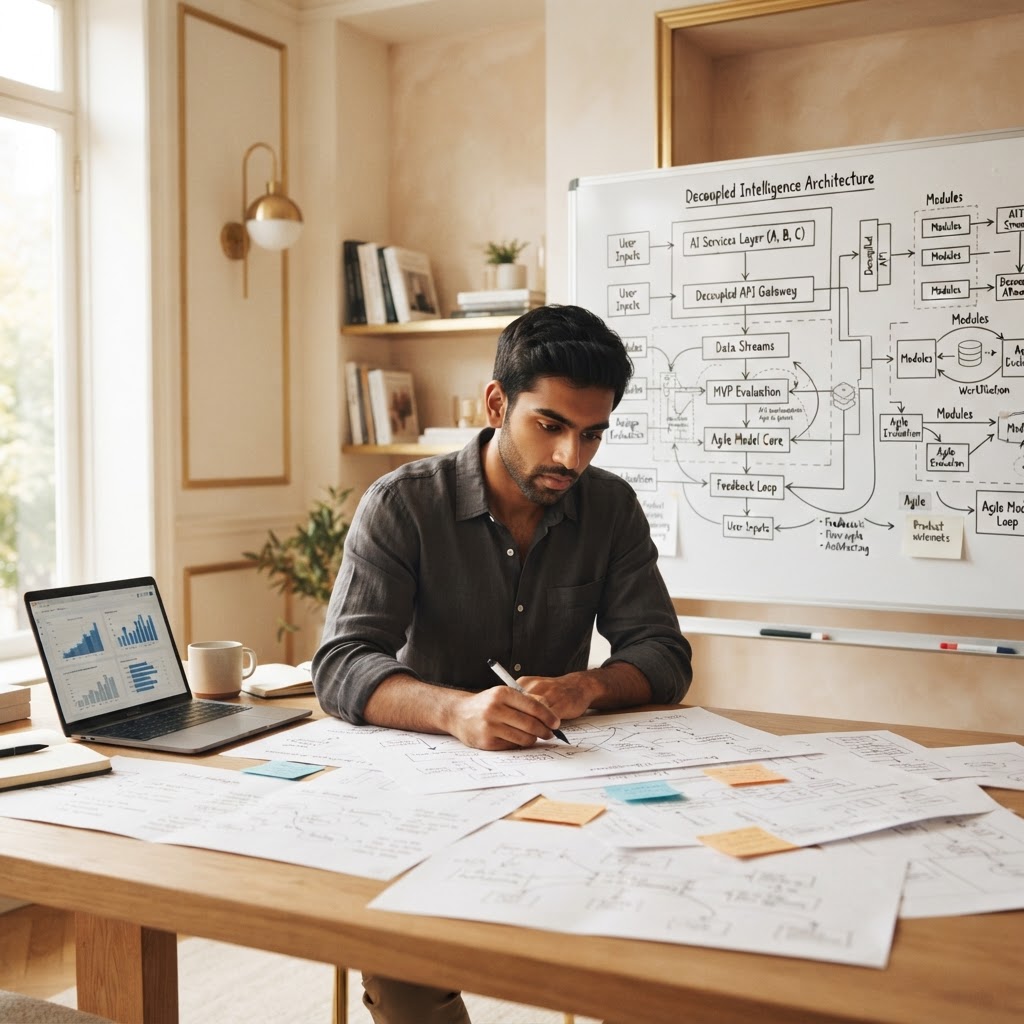
The Decoupled Intelligence Strategy: Architecting AI MVPs for Model Agility
AI MVPs fail founders when the model and the application are welded together, turning every provider switch into a rebuild. This guide shows how to architect a decoupled model layer, with a router pattern and hypothetical example, so you can swap AI models without rewriting your product.
The Invalidation Mindset: Moving Beyond Confirmation Bias in Startup Discovery
Most startup validation fails because founders design tests to confirm what they already believe rather than expose weaknesses. This article lays out a practical protocol for seeking disconfirming evidence before committing to a build.
The Agentic Perimeter: A 2026 Framework for Securing Autonomous Workflows
Agentic applications operate across APIs, databases, and code execution environments without constant human oversight, which means security has to be designed in from the start rather than added later. This article lays out a practical, tiered framework founders can use to scope permissions, defend against prompt injection, and monitor agent behavior at runtime.
The Rebuild-vs-Extend Dilemma: When to Transition Your AI-Generated MVP to Production Code
AI-generated MVPs are great for validation but not built to carry real customers, and the rebuild decision should be made component by component rather than all at once. This article gives founders a concrete framework for deciding which parts of their vibe-coded MVP need production-grade rework first.
The Outcome-Based ROI Framework: Moving Beyond Token-Cost Metrics for Agentic MVPs
Traditional SaaS metrics like seat counts and token usage don't capture the value of autonomous agentic workflows. This article outlines an outcome-based ROI framework built around baselines, cycle time, and error rate improvements.
The Agency Tax: How to Quantify Hidden Costs in Agentic MVPs
Founders often measure agentic MVPs by task completion alone, missing the hidden verification and re-run costs that can quietly erode margins at scale. This article shows how to instrument, measure, and control the 'agency tax' before it becomes an unaffordable surprise.
The Modular Monolith Strategy: Balancing MVP Speed with Future Pivotability
Learn why a modular monolith, not microservices, is usually the right architecture for an early-stage MVP, and how to set module boundaries that survive a pivot. Includes a hypothetical example, tradeoffs, common mistakes, and a founder checklist.
The Evidence Ladder: How to Rank Validation Signals From Weak to Strong
Most founders confuse activity with proof, mistaking waitlist signups for real demand. An evidence ladder ranks validation signals from weak opinions to strong resource commitments, helping founders know when they've actually earned the right to build.
Beyond Task Success: A 2026 Framework for Measuring Agentic Reliability and ROI
Task success rates hide the variance, cost drift, and safety gaps that determine whether an agentic workflow is actually production-ready. This article outlines a multidimensional reliability framework plus cost metrics like ACCT and AVM to help founders measure agentic AI honestly.
The AI Debt Reckoning: Identifying and Managing Hidden Technical Debt in 2026
AI coding agents can produce code that passes tests today but hides architectural assumptions that break the moment your product changes shape. This guide gives founders a practical framework for telling reasonable early trade-offs apart from dangerous hidden AI debt.